NeurIPS 2026 OralCorresponding author
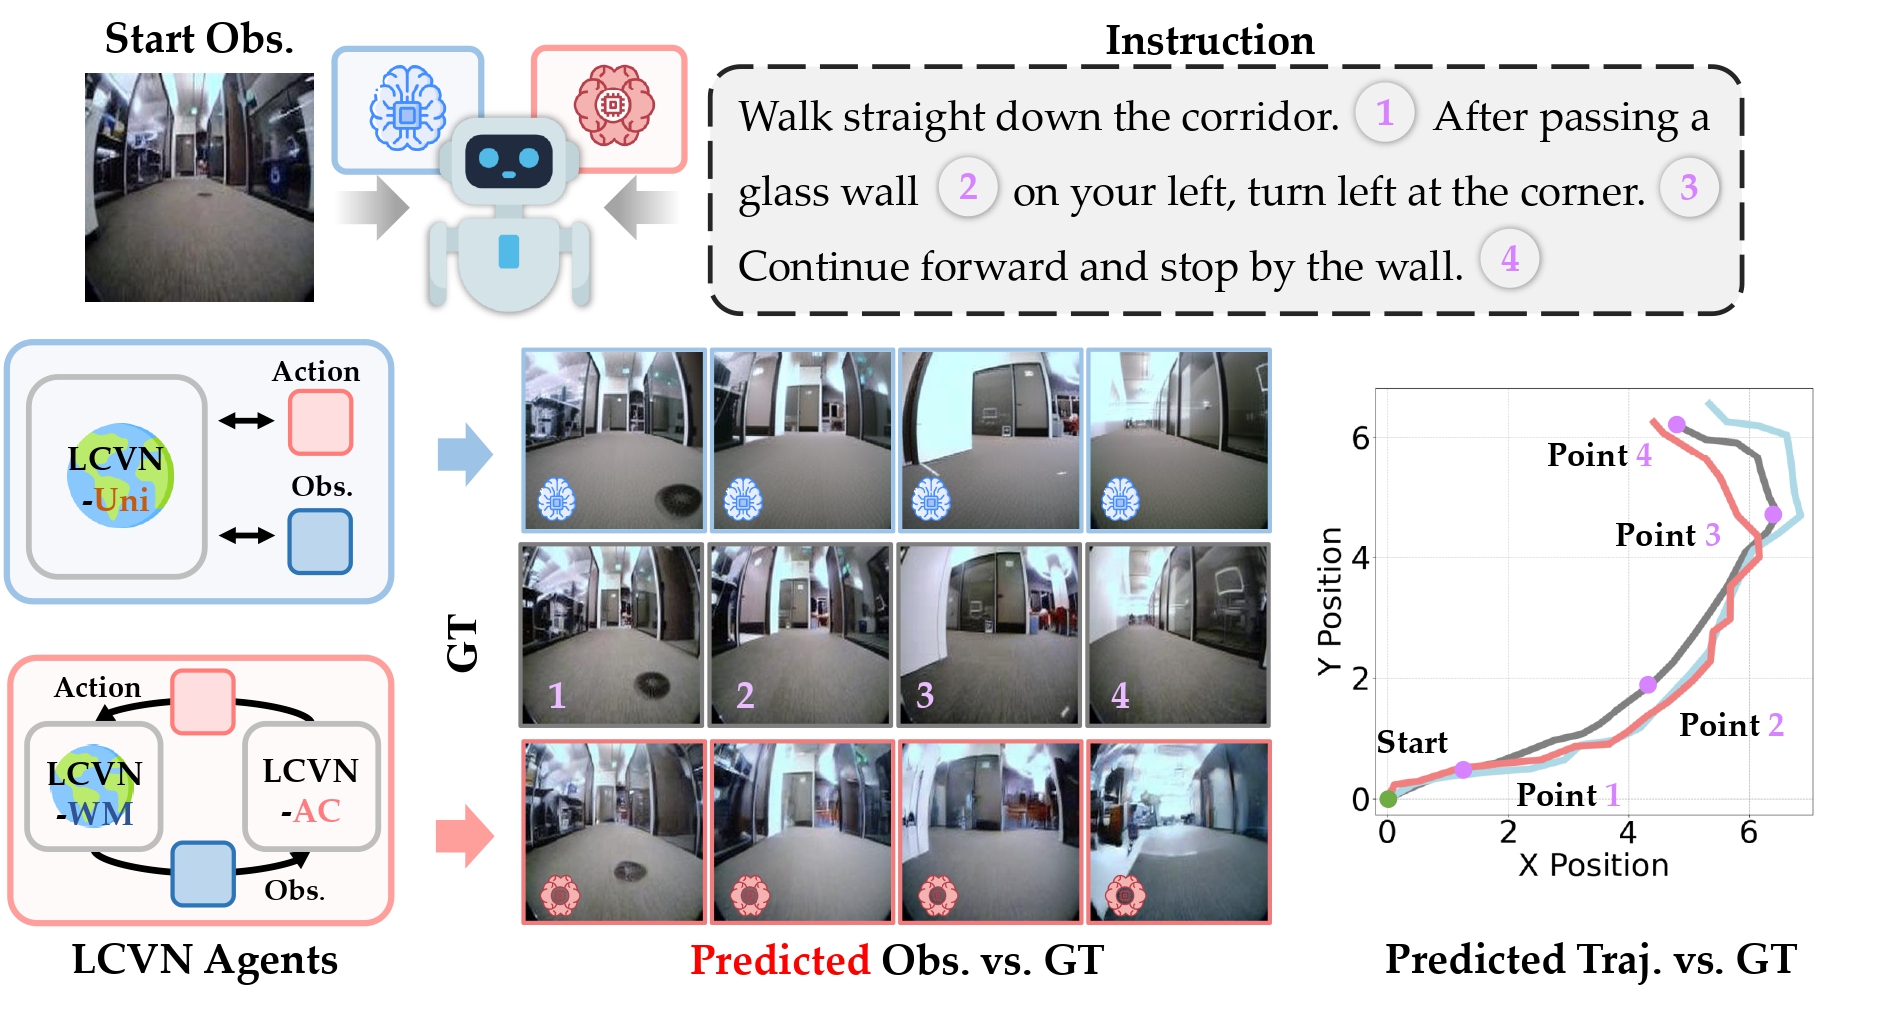
Language-Conditioned World Modeling for Visual Navigation
Connects language instructions, imagined future observations, and action selection in a world model for visual navigation.
Representative contributions in world models, visual perception, multimodal reasoning, and efficient learning.
From human-aware navigation benchmarks to memory, prediction, and language-conditioned planning.
NeurIPS 2026 OralCorresponding author
Connects language instructions, imagined future observations, and action selection in a world model for visual navigation.
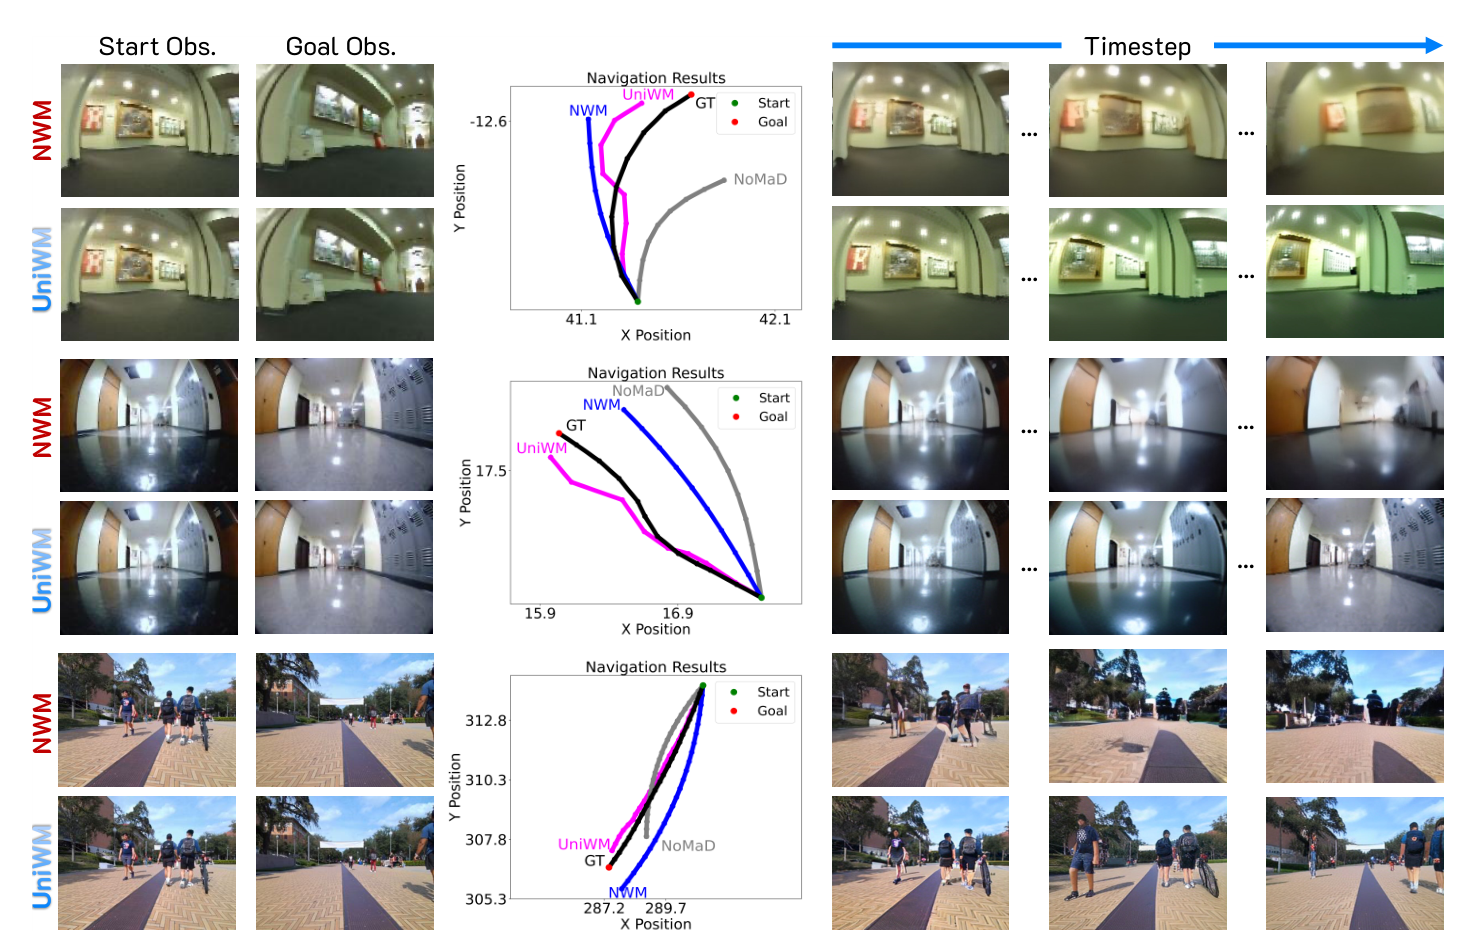
ECCV 2026 Corresponding author
Combines memory, future prediction, and planning to navigate through unfamiliar environments.
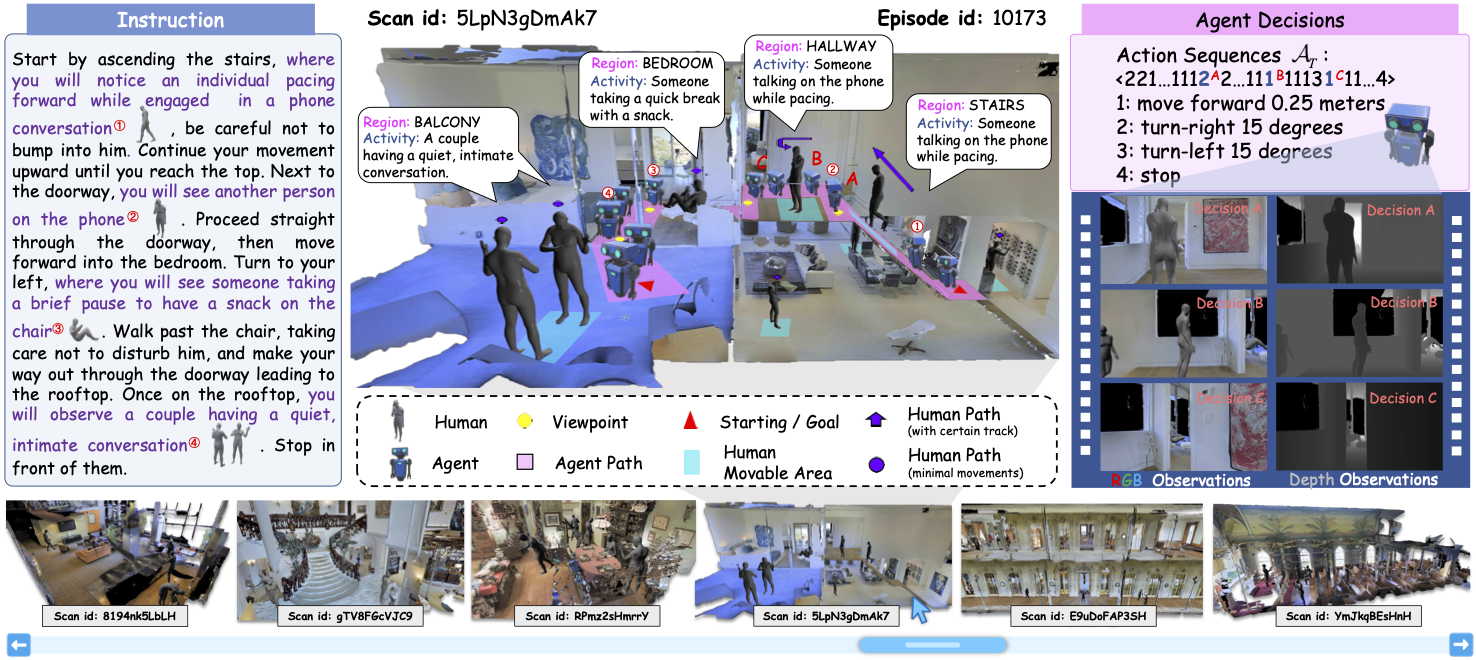
IROS 2026 Corresponding author
Provides a benchmark and evaluation platform for navigation amid dynamic interactions with multiple people.
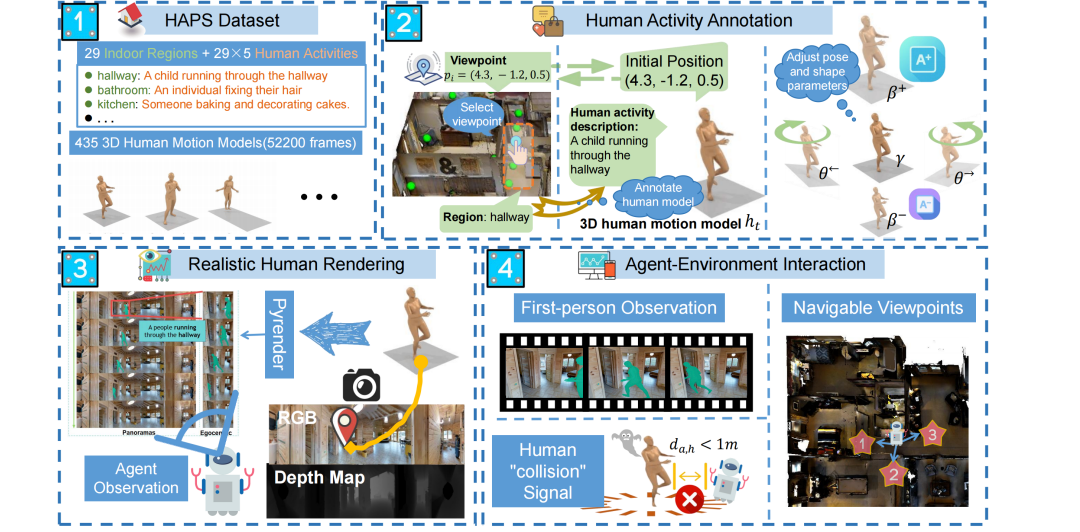
NeurIPS 2024 · Datasets and Benchmarks Spotlight Co-first authorCorresponding author
Introduces human-aware vision-and-language navigation, bringing moving people into embodied navigation tasks.
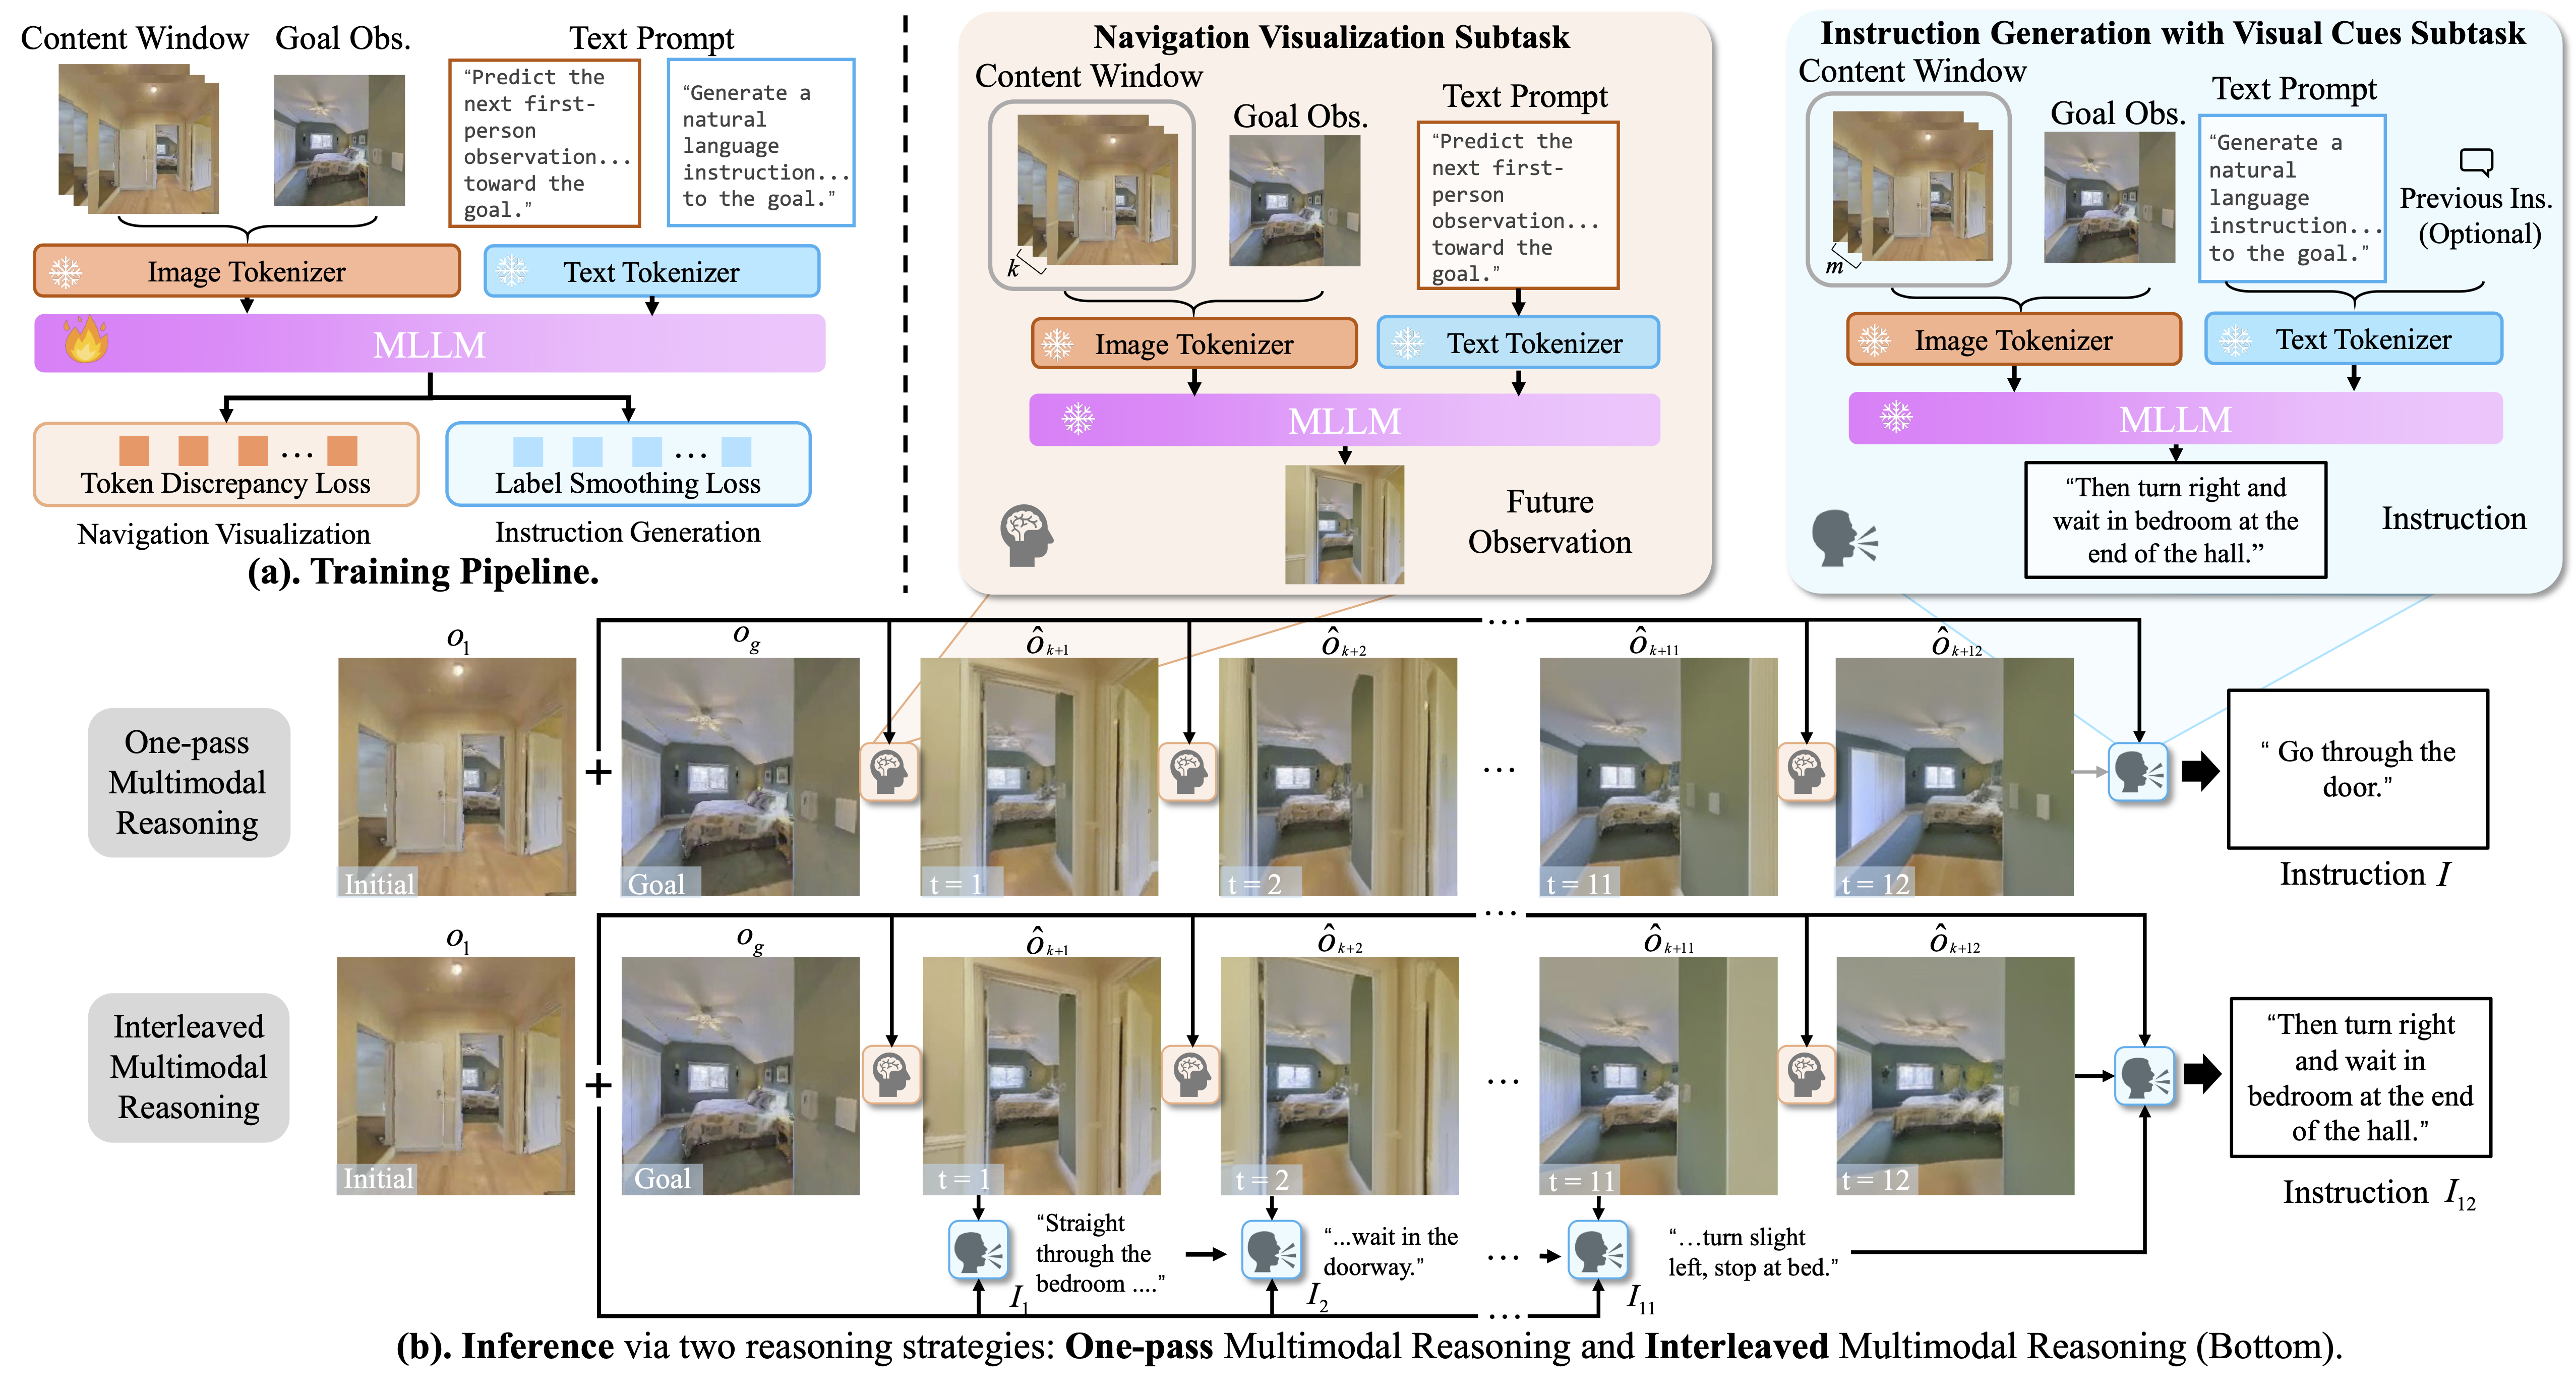
Findings of ACL 2026 Corresponding author
Generates goal-conditioned navigation instructions through multimodal reasoning about routes and visual observations.
Contributions to crowd counting, human action and pose understanding, streaming perception, and cross-domain visual retrieval.
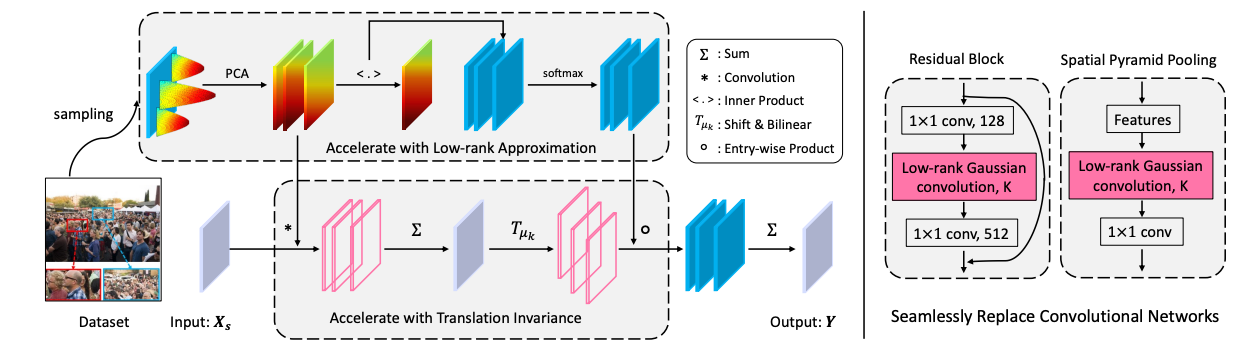
CVPR 2022 First author
Revisits spatial invariance in convolutional networks to improve object counting across varied scenes.
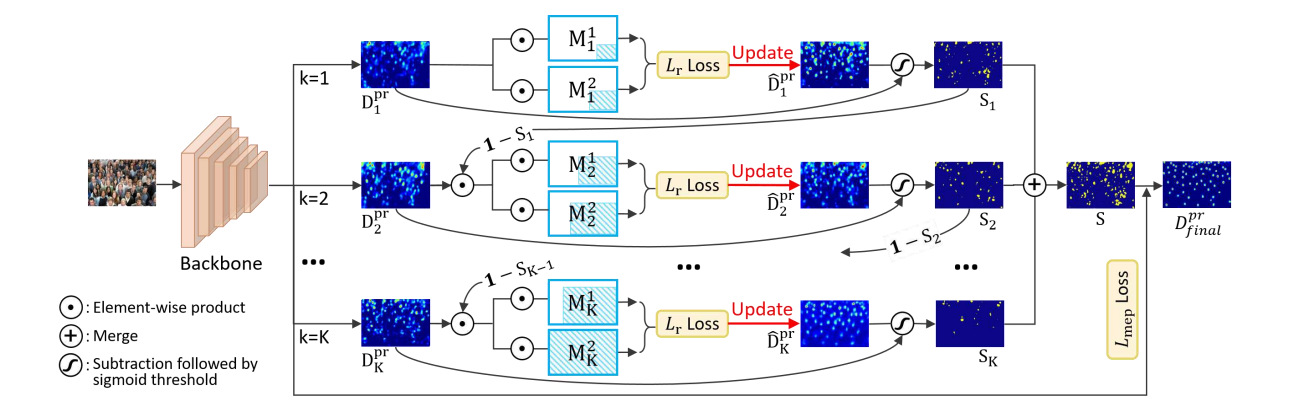
ICCV 2019 OralCo-first author
Introduces spatially aware density estimation and a pixel-level discrepancy loss to improve crowd counting in dense, noisy scenes.
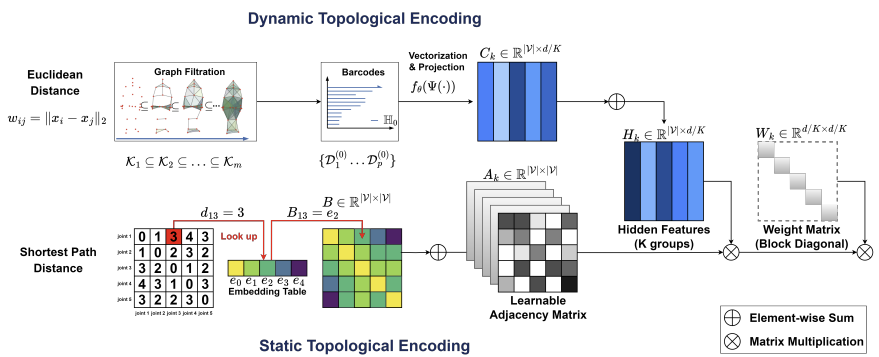
CVPR 2024 Corresponding author
Preserves skeletal topology with geometric encodings and efficient graph convolutions for human action recognition.
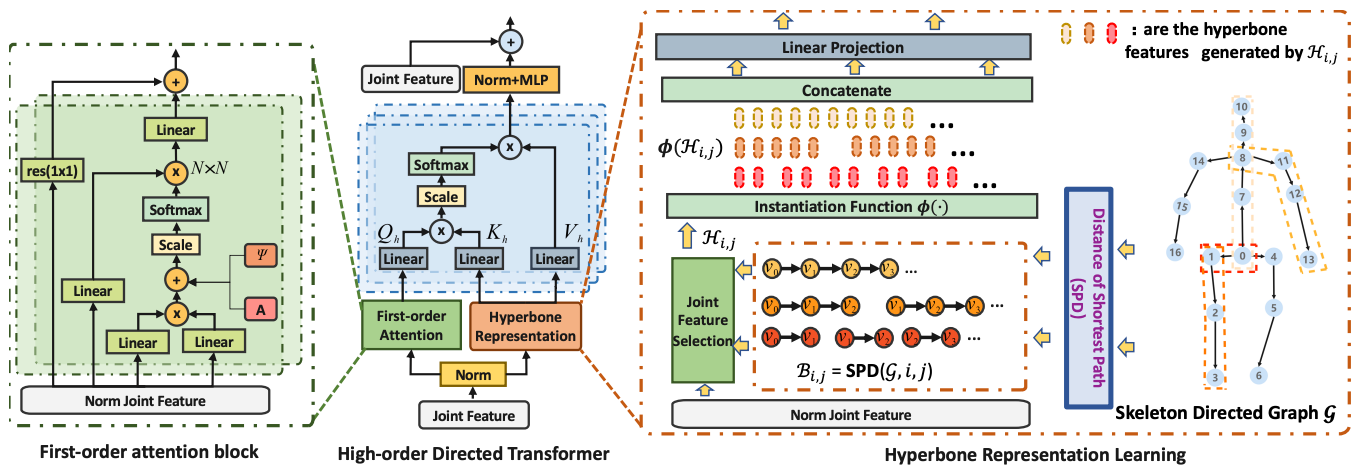
IJCAI 2023 Co-first author
Models higher-order relations among joints and bones for efficient, accurate 3D human pose estimation.
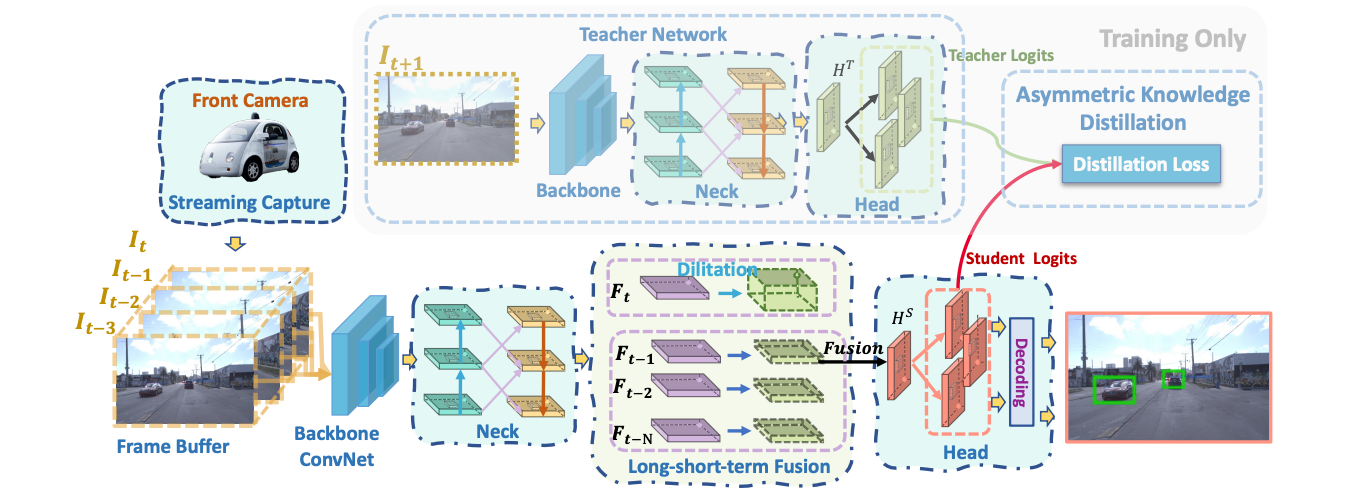
IJCAI 2023 Corresponding author
Optimizes streaming perception for autonomous driving, accounting for both detection quality and inference latency.
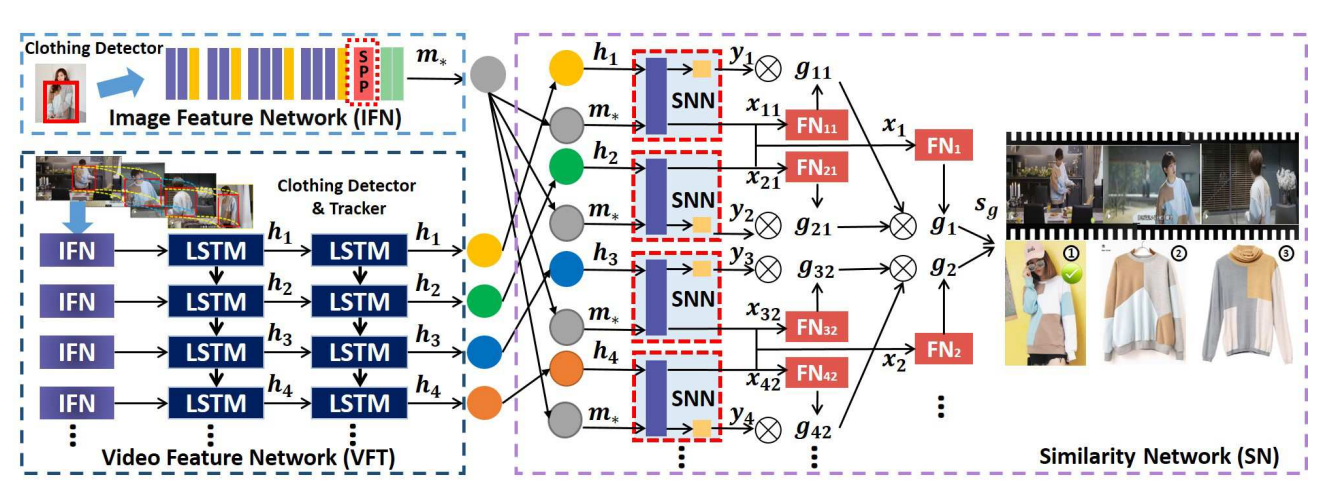
CVPR 2017 First author
Introduces cross-domain video-to-product retrieval, matching clothing in video sequences to the same items in online shops.
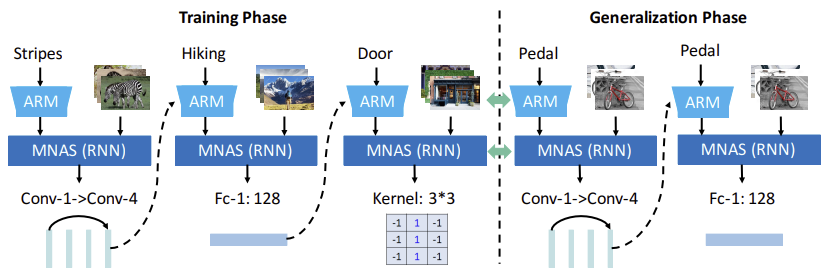
ACM Multimedia 2018 First author
Combines multitask learning and neural architecture search to transfer attribute representations across animals, objects, and scenes.
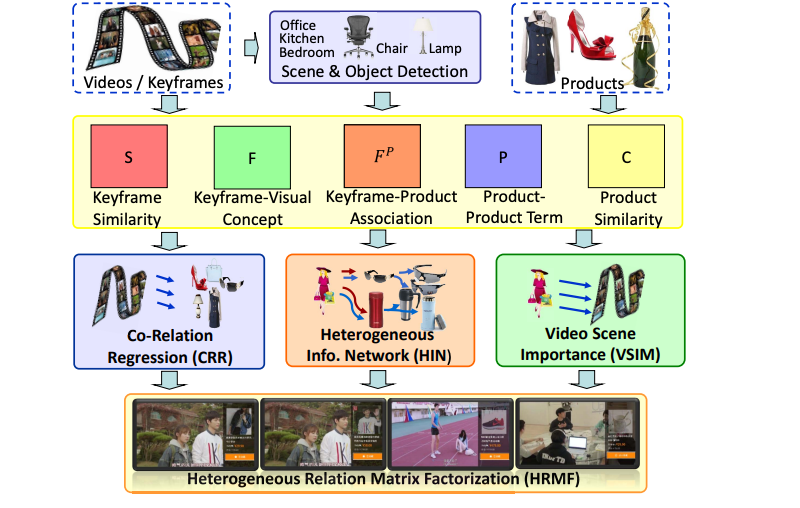
IEEE Transactions on Multimedia 2017 First author
Extends video advertising to large-scale deployment through incremental semantic modeling, cross-domain preference learning, and distributed optimization.
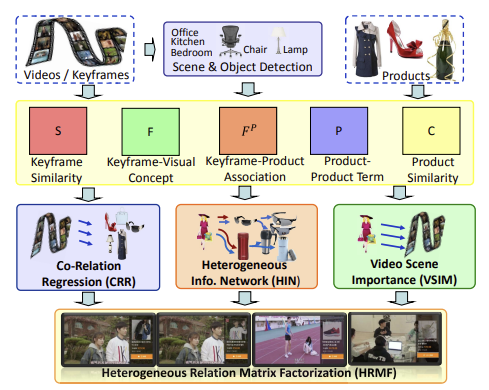
ACM Multimedia 2016 ACM SCF Best Student Paper AwardFirst author
Connects video semantics, shopping preferences, and viewing behavior to recommend products at relevant moments in a video.
Models and datasets for understanding charts, situations, emotions, and events, and for generating images and human motion.
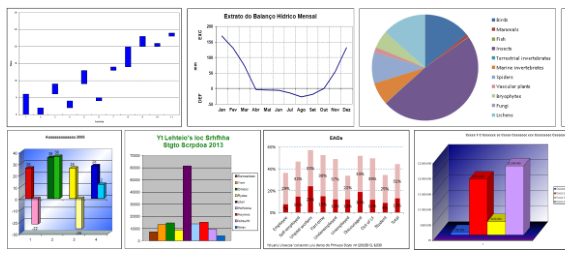
ICCV 2023 First author
Unifies chart structure recovery and chart understanding without hand-crafted heuristic rules.
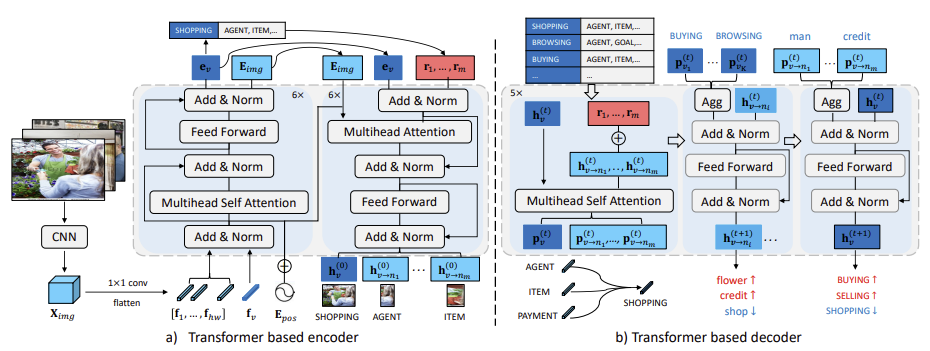
ACM Multimedia 2022 First author
Jointly reasons about actions, participants, and their locations to recognize grounded visual situations.
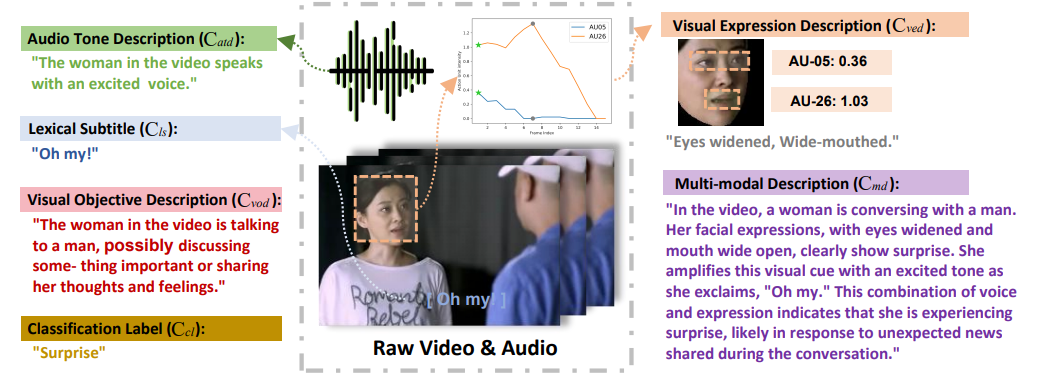
NeurIPS 2024 Co-first authorCo-corresponding author
Combines audio, visual, and textual evidence for instruction-following emotion recognition and reasoning.
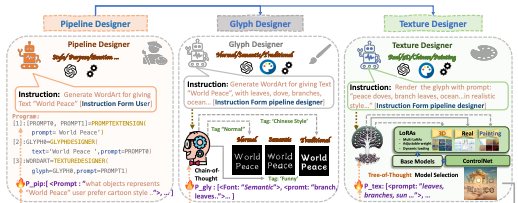
ICLR 2025 Corresponding author
Integrates user intent, glyph design, and texture generation for multilingual artistic typography.
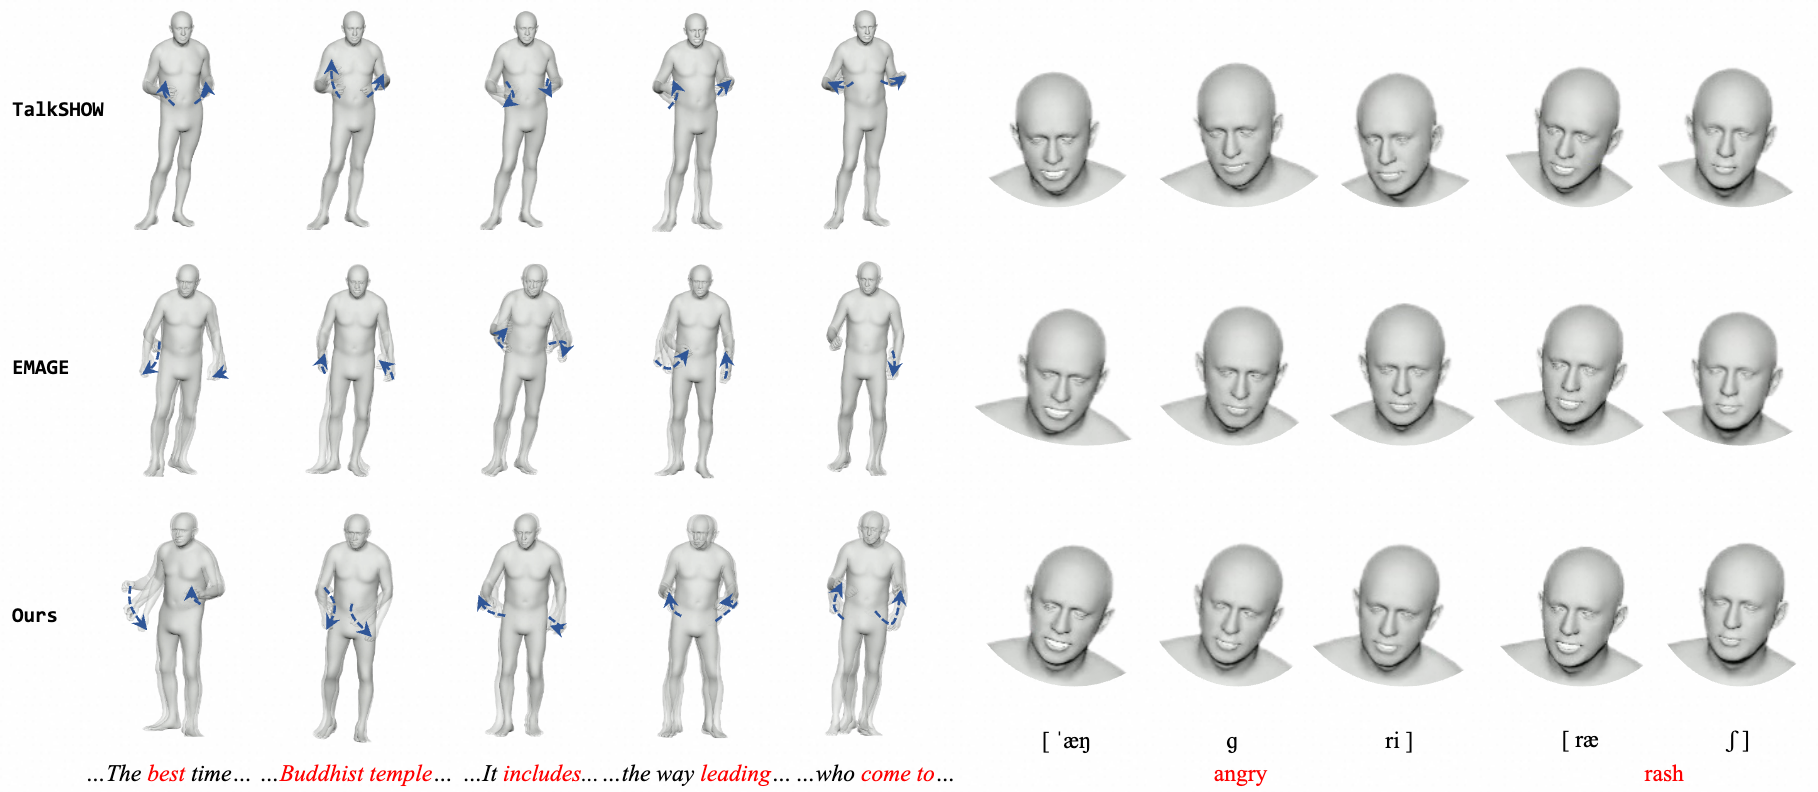
IEEE TPAMI 2025 · Early access Co-first author
Generates coordinated facial expressions and body motion from speech, with efficient adaptation to new identities and emotions.
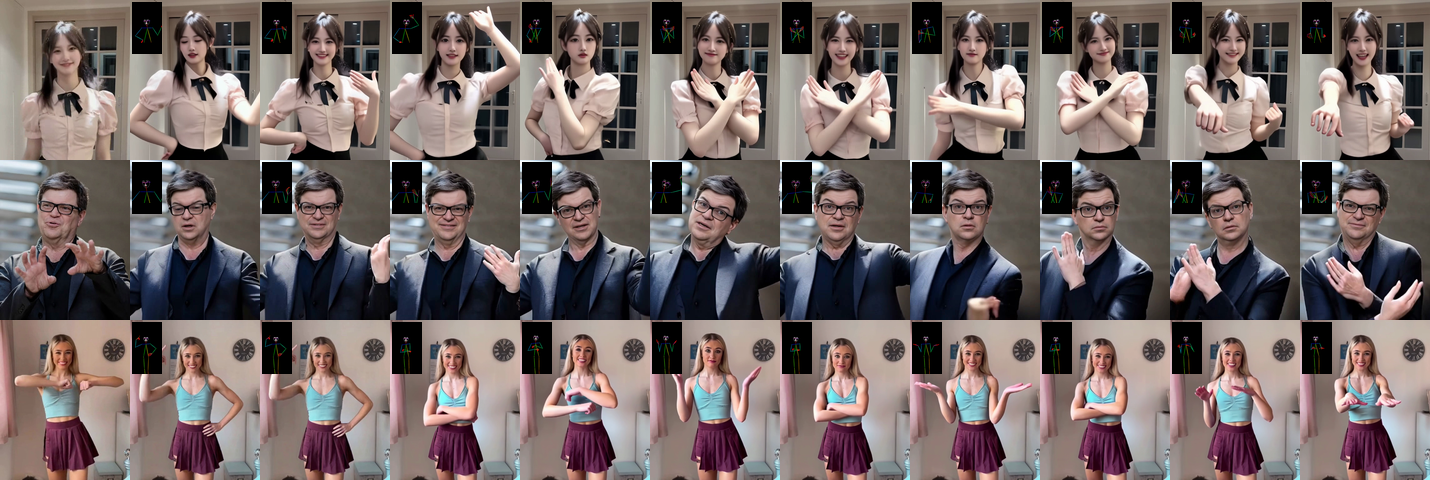
CVPR 2025
Generates human animation from a reference image while preserving the subject’s identity.
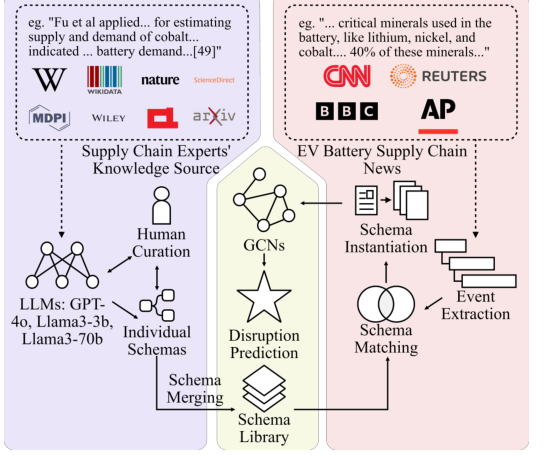
EMNLP 2024 · Industry Track Co-first author
Uses language models to induce event schemas for predicting disruptions in electric-vehicle battery supply chains.
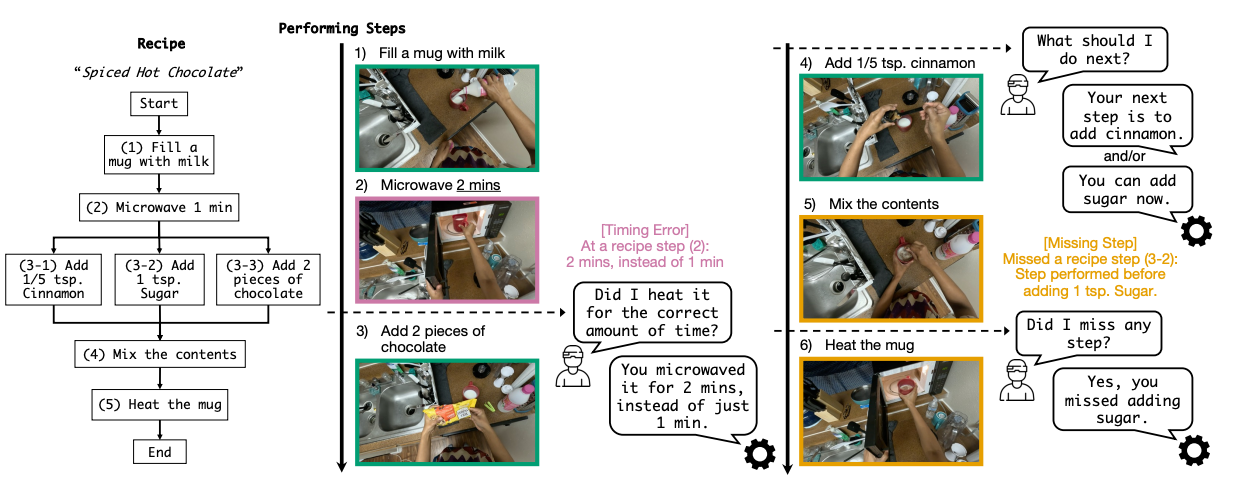
NAACL 2025
Introduces multimodal question answering for understanding procedural activities and their execution.
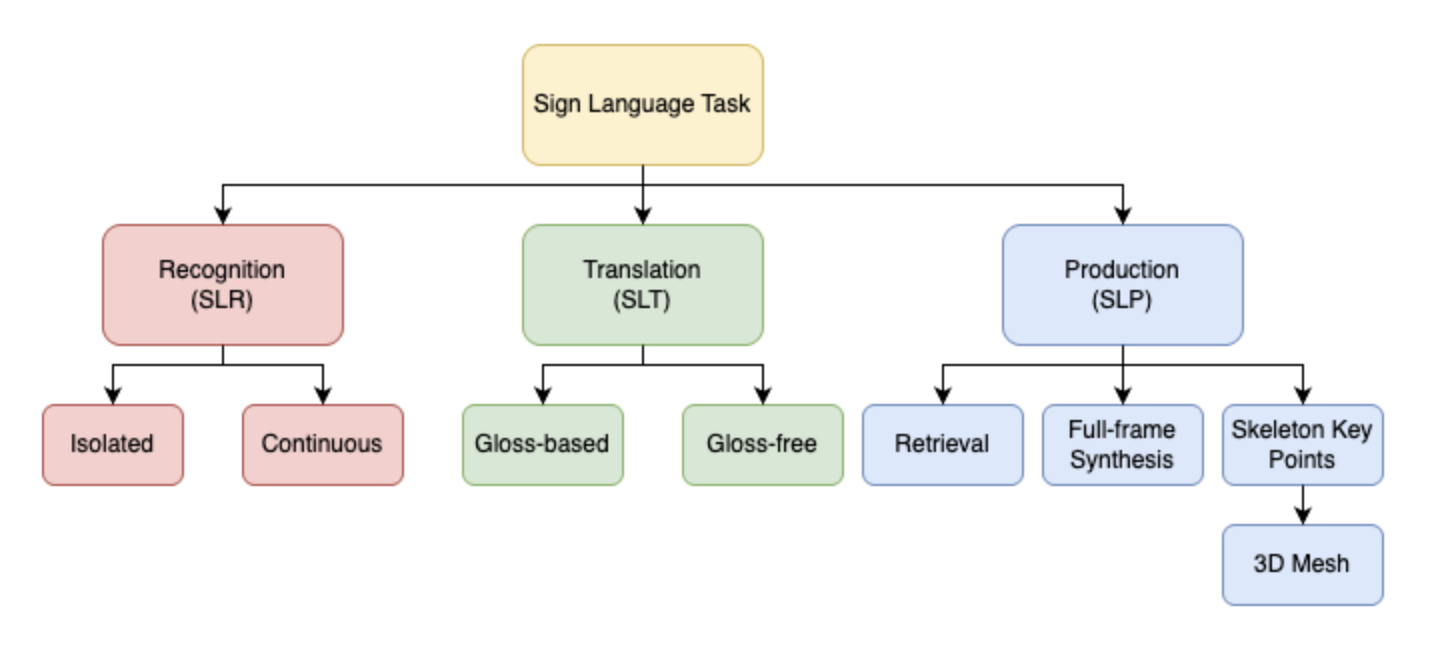
ACL 2026 Corresponding author
Organizes 120 datasets across 35 sign languages and introduces a 24-field datasheet for consistent documentation and evaluation.
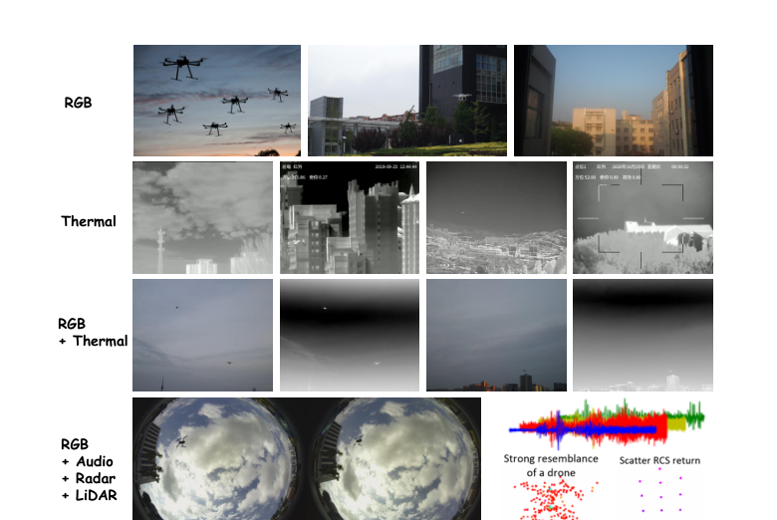
CVPR 2025 · Anti-UAV Workshop Best Paper Award Corresponding author
Systematizes anti-UAV methods, sensing datasets, evaluation practices, and open research challenges.
Faster inference, stronger representations, and reliable adaptation of foundation models.
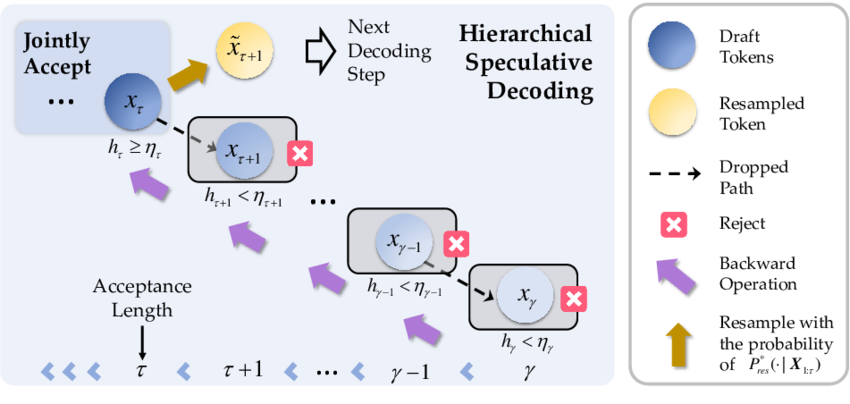
ICLR 2026 OralCo-corresponding author
Accelerates language-model inference through hierarchical speculative decoding while preserving the target output distribution.
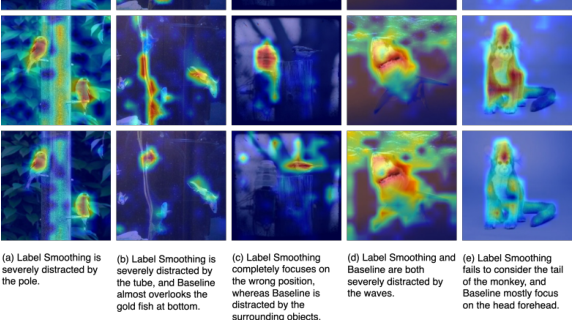
NeurIPS 2025 OralCorresponding author
Addresses representation collapse caused by label smoothing while retaining the benefits of regularization.
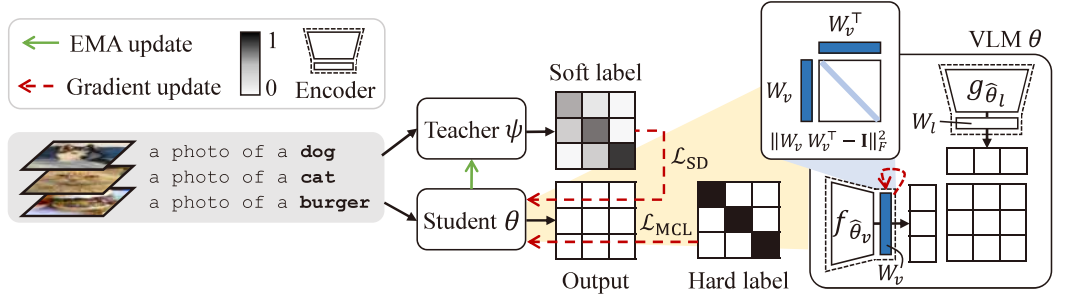
NeurIPS 2024 Co-corresponding author
Develops fine-tuning methods that improve both prediction accuracy and confidence calibration under distribution shift.
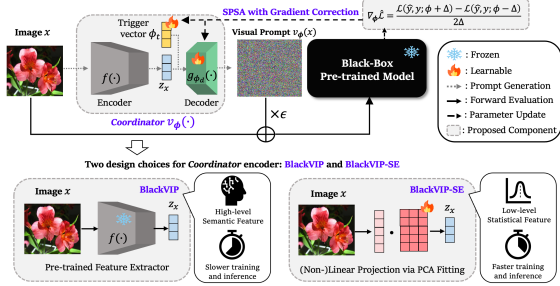
IEEE TPAMI 2026
Adapts black-box foundation models through visual prompts, with parameter-efficient learning and robustness analysis.